BSEtec specializes in building comprehensive, correlated, and actionable observability solutions and reliability engineering solutions that instrument systems, detect anomalies, and surface root cause before an outage escalates — without engineers drowning in disconnected logs, metrics, and alerts. Our observability and reliability engineering solutions enable organizations to deploy monitoring, alerting, and AIOps observability-driven correlation with defined boundaries and real accountability. With deep cloud reliability engineering expertise, BSEtec is your trusted partner in building observability infrastructure your on-call teams can actually depend on.
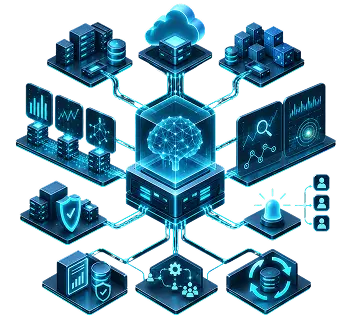
Tailored observability architecture built around your specific systems, whether distributed microservices, legacy infrastructure, or hybrid cloud environments.
Observability infrastructure with unified logs, metrics, and traces, plus AIOps event correlation built in from day one — visibility with defined boundaries for faster root-cause analysis.
Detection models tested extensively against historical incident data and simulated failure conditions before being deployed as production alerts through automated anomaly detection.
Dedicated reliability engineering services and failure-mode analysis across every critical system, mapped against defined SLOs and error budgets.
Live real-time observability monitoring with explicit on-call escalation, so any detected anomaly routes to the right responder immediately instead of sitting unnoticed in a dashboard.
Seamless integration with existing cloud providers, logging stacks, and incident management tools, with continued technical support as your cloud observability platform operates.
We connect logs, metrics, and traces into unified events, so on-call engineers get one clear signal instead of dozens of disconnected alerts through observability and monitoring solutions.
We define error budgets and thresholds from your actual historical performance, not arbitrary industry defaults through SLO monitoring and management.
Every AI anomaly detection model is validated against your historical incident data, so it catches real failure patterns before going live.
We route alerts directly to the responsible responder, cutting the time between detection and action through automated incident management.
We build root cause analysis solutions to trace issues back to their true origin, so fixes address the actual failure, not just its visible effect.
We stay engaged as your system complexity grows, refining SLOs and detection logic instead of leaving you with a static setup through continuous reliability engineering.

No: 2300 Stanwell dr suite A, concord California 94520, United states.
(+1) 3372-837-130
No: 8 rue Charles Martel, -1 Level, 1000 brussels Belgium.
(+32) 467-616-037
No: 242, Morning star Level 3, 6th cross, Indiranagar First Stage, Bangalore - 560038, Karnataka, India.
(+91) 950-090-2222No: 8, 20 Feet Extension Road, 70 Feet Road, Ellis Nagar, Madurai - 625016.
(+91) 967-771-7038